NoSB Robotics
WORK

BUILT
TO MOVE.

We tackle real, unresolved problems in robotics, building practical methods across perception, decision-making and control, then validating them on physical systems in complex environments.

Robot Control

Practical approaches to perception, motion and whole-body control for real robotic systems.
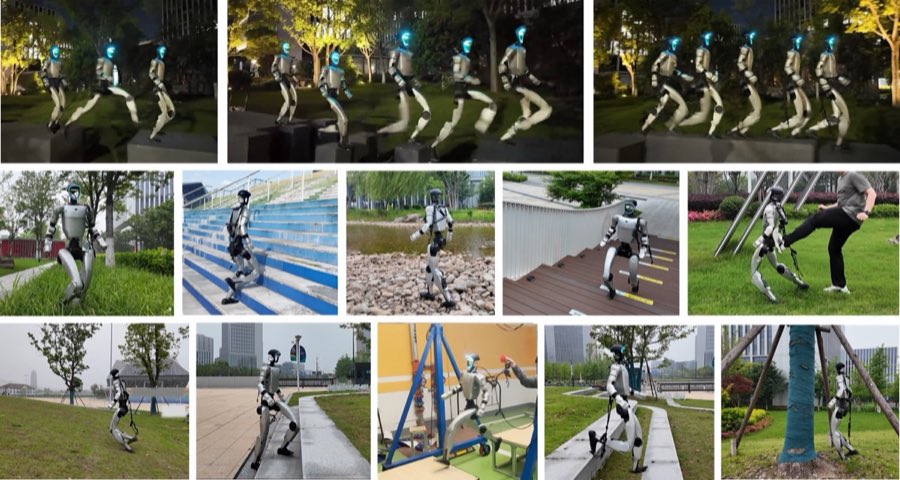
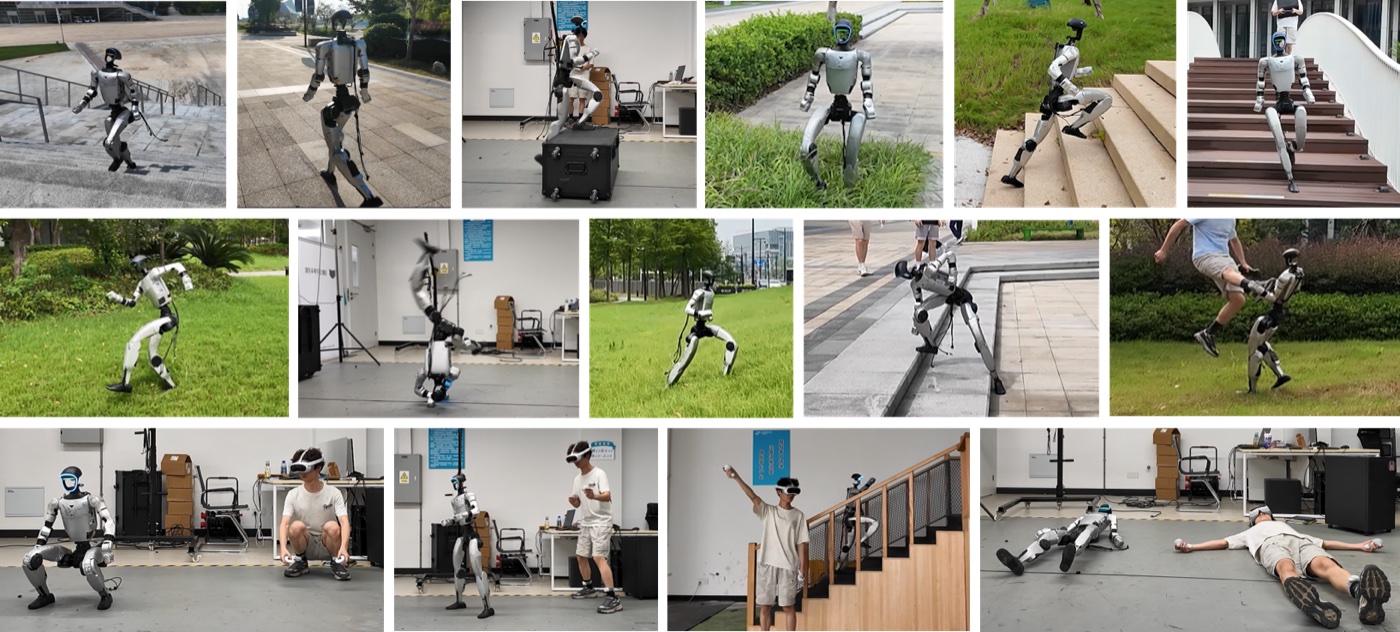
PGMT 人形机器人在运动、遥操作和恢复任务中的实验

SEP 2026 · ARXIV PREPRINT

PGMT

Perceptive General Motion Tracking for Humanoid Robots

Hongyi Li, LI Peizhuo, Yucheng Tao, et al.

A unified perceptive policy tracks diverse whole-body motions while adapting to complex terrain, supporting locomotion, teleoperation and recovery.

TAGA 人形机器人在多种户外地形上的运动实验

JUN 2026 · UNDER REVIEW

TAGA

Terrain-aware Active Gaze Learning for Generalizable Agile Humanoid Locomotion

LI Peizhuo*, Hongyi Li*, Mingfeng Fan*, et al.

Terrain-aware active gaze lets humanoids anticipate footholds and retain agile locomotion across unfamiliar terrain.

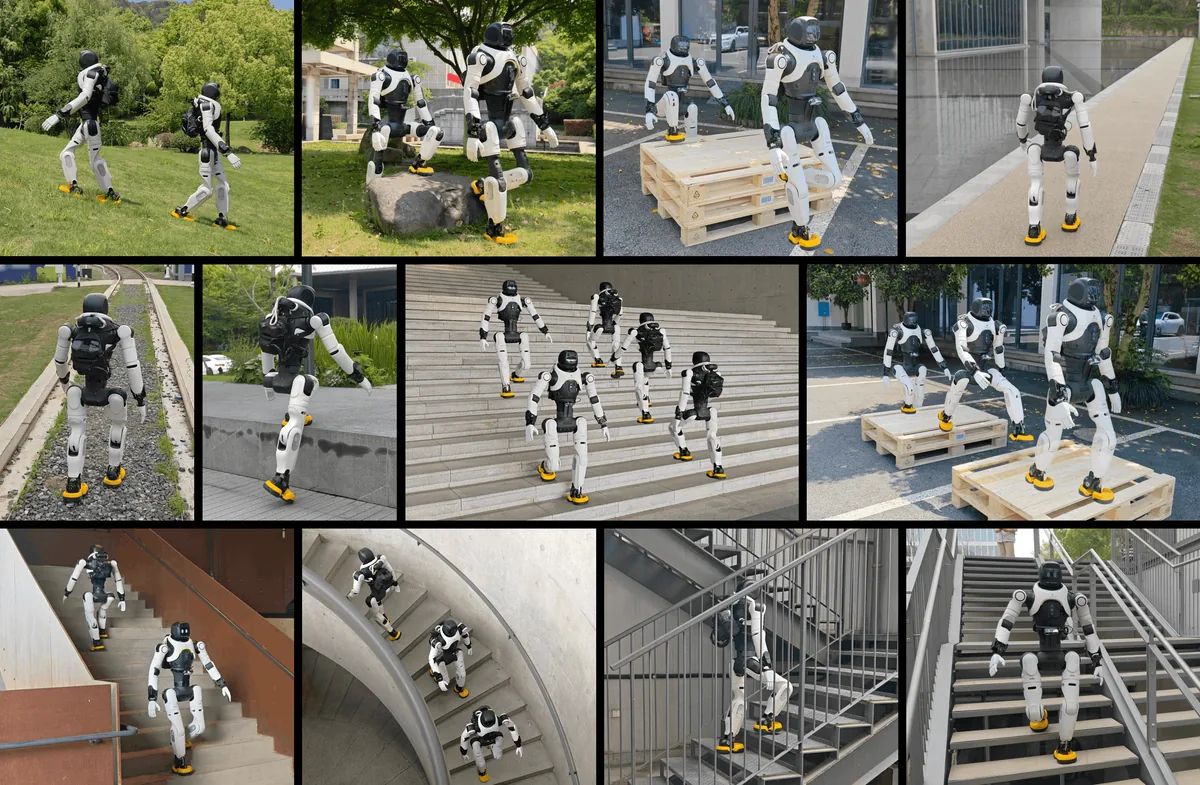
SSR 论文图 1:人形机器人在开放世界地形中的运动实验

2026 · CoRL

SSR

Scaling Surefooted and Symmetric Humanoid Traversal to the Open World

Ruiqi Yu*, Yiwen Wang*, Yuan Hao, Jun Wu, Qiuguo Zhu

An efficient egocentric vision framework for safe, symmetric and human-like humanoid traversal across stairs, gaps, high platforms and long outdoor routes.

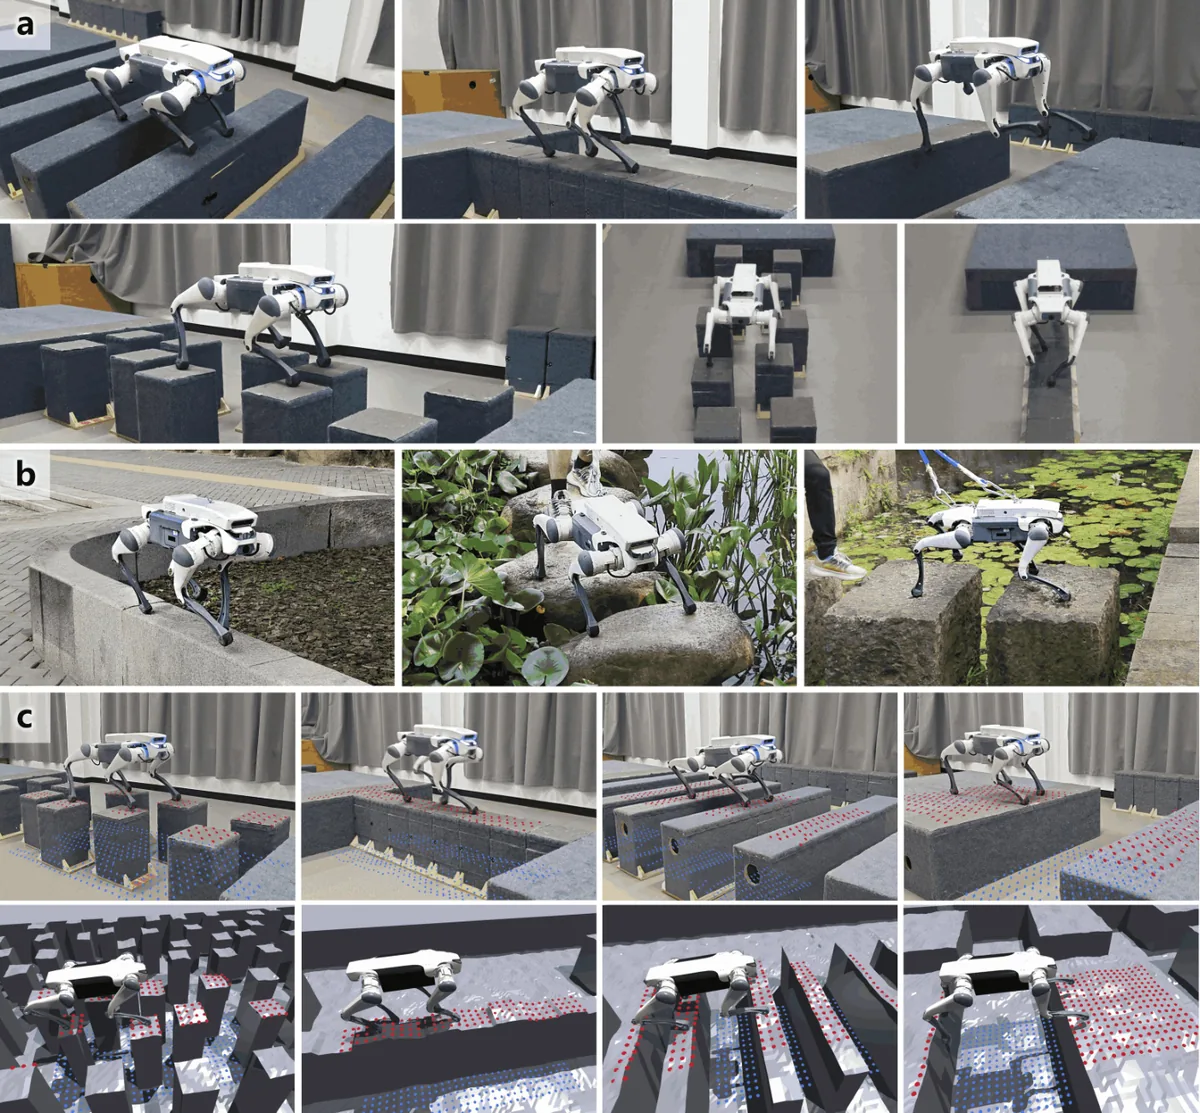
START 论文图 1:四足机器人跨越稀疏落脚点及地形重建

DEC 2025 · IEEE RA-L

START

Traversing Sparse Footholds with Terrain Reconstruction

Ruiqi Yu, Qianshi Wang, Hongyi Li, Zheng Jun, et al.

A single-stage framework reconstructs local terrain from onboard vision and proprioception for precise, robust quadruped traversal on sparse footholds.

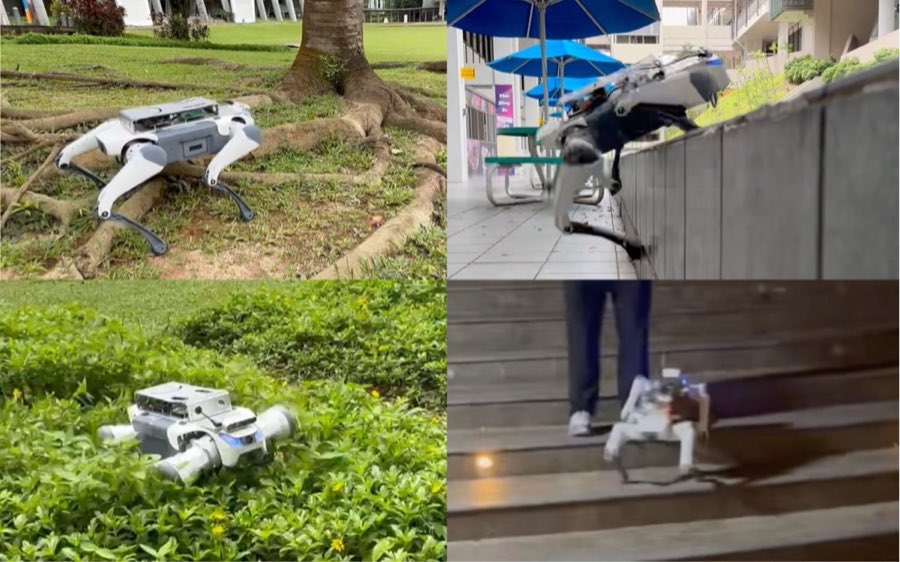
KiVi 四足机器人在树根、草地、台阶和墙边的运动实验

SEP 2025 · IEEE/RSJ IROS

KiVi

Kinesthetic-Visuospatial Integration for Dynamic and Safe Egocentric Legged Locomotion

LI Peizhuo*, Hongyi Li*, Yuxuan Ma*, et al.

Kinesthetic and visuospatial cues are fused for dynamic, safe and egocentric quadruped locomotion.

Aerial Robotics

Motion planning and control for agile, autonomous aerial robots.

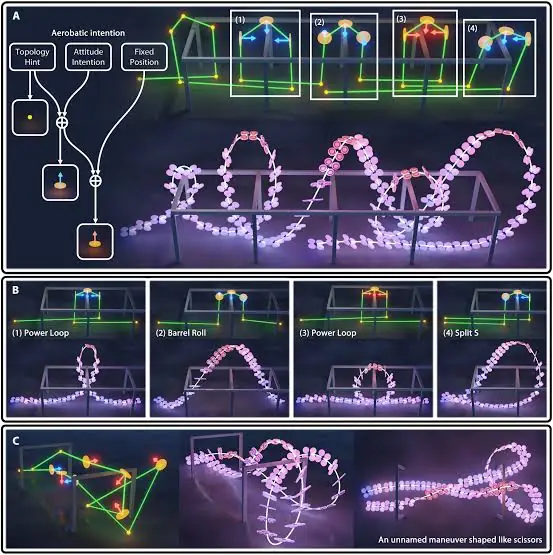
四旋翼自主自由式飞行论文图:特技意图与轨迹生成,以及翻滚、筋斗和剪刀形飞行实验

APR 2025 · SCIENCE ROBOTICS

Unlocking aerobatic potential of quadcopters: Autonomous freestyle flight generation and execution

Mingyang Wang, Qianhao Wang, Ze Wang, et al.

An aerobatic-intention representation and spatial-temporal trajectory optimization generate feasible, collision-free quadcopter freestyle maneuvers in obstacle-dense environments.

Multi-Agent

Learning to coordinate missions and reason about interactions among agents.

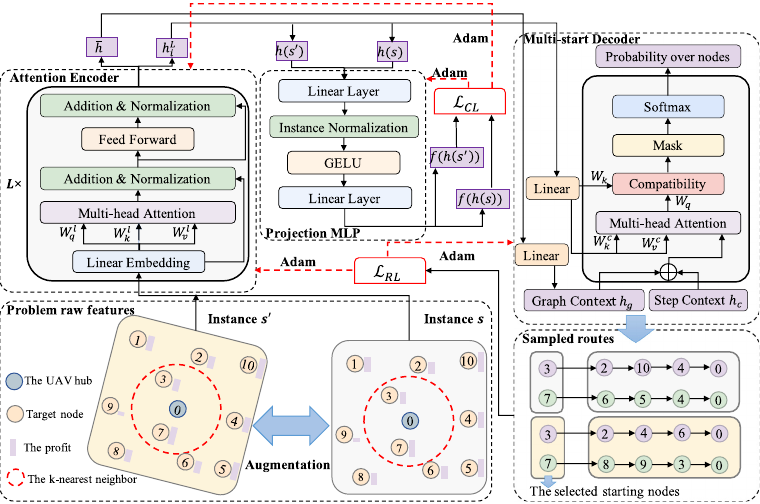
多无人机任务规划的 NNO-DRL 方法图

2025 · SWARM AND EVOLUTIONARY COMPUTATION

Multi-UAV reconnaissance mission planning via deep reinforcement learning with simulated annealing

Mingfeng Fan, Huan Liu, Guohua Wu, et al.

Deep reinforcement learning and simulated annealing alternate target allocation and route planning for multi-UAV reconnaissance missions.

Robotic Task Planning

Learning efficient task sequences and collision-free paths for robotic systems.
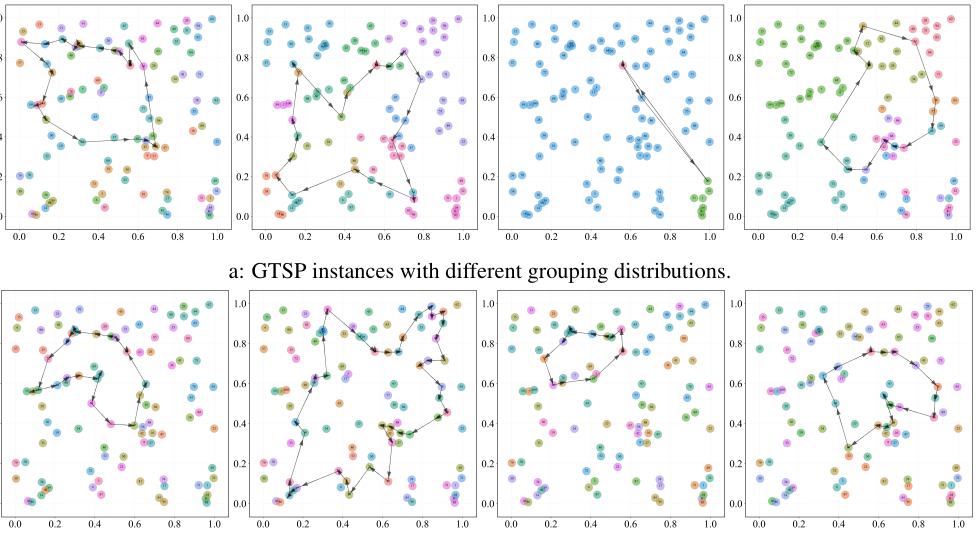
MMFL 彩色任务规划图:不同目标分组下的路径求解结果

2025 · CONFERENCE ON ROBOT LEARNING

Multimodal Fused Learning for Solving the Generalized Traveling Salesman Problem in Robotic Task Planning

Jiaqi Cheng, Mingfeng Fan, Xuefeng Zhang, et al.

Graph and image representations are fused to solve generalized traveling salesman problems for real-time robotic task planning.
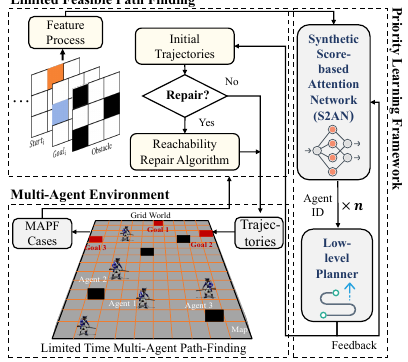
多智能体路径规划与注意力优先级学习框架

2024 · AAMAS

Attention-based Priority Learning for Limited Time Multi-Agent Path Finding

Yibin Yang*, Mingfeng Fan*, Chengyang He, et al.

Attention-based reinforcement learning learns agent priorities for scalable, collision-free path planning under limited computation time.

Autonomous Vehicles

Trajectory prediction and safe planning for autonomous vehicles.

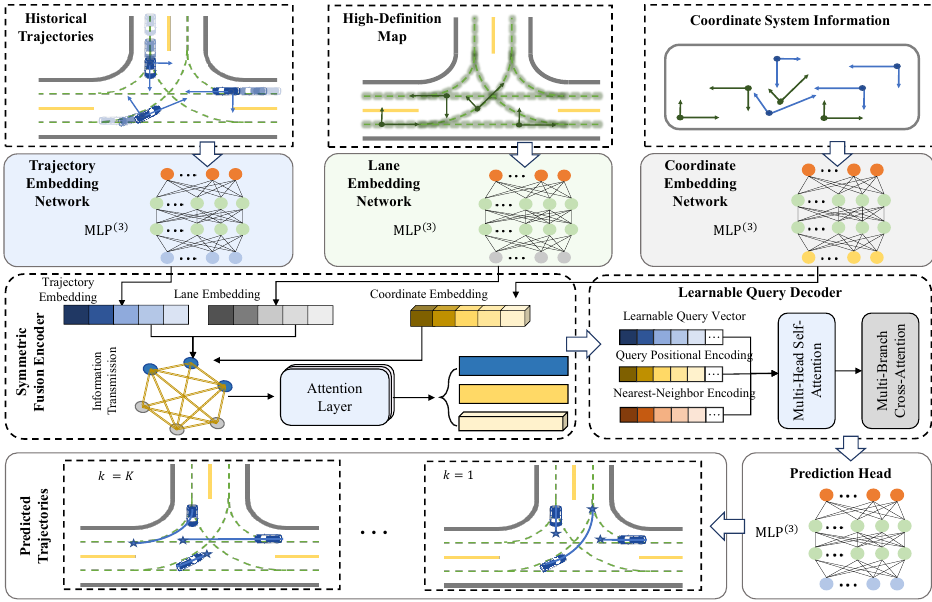
CogDrive 多模态预测网络方法图

2026 · COMMUNICATIONS IN TRANSPORTATION RESEARCH

CogDrive: Cognition-driven multimodal prediction-planning fusion for safe autonomy

Heye Huang, Yibin Yang, Mingfeng Fan, et al.

Cognitive interaction modeling connects multimodal trajectory prediction with safety-aware planning in mixed traffic.

VLA

Vision-language-action models for cross-embodiment robot learning.

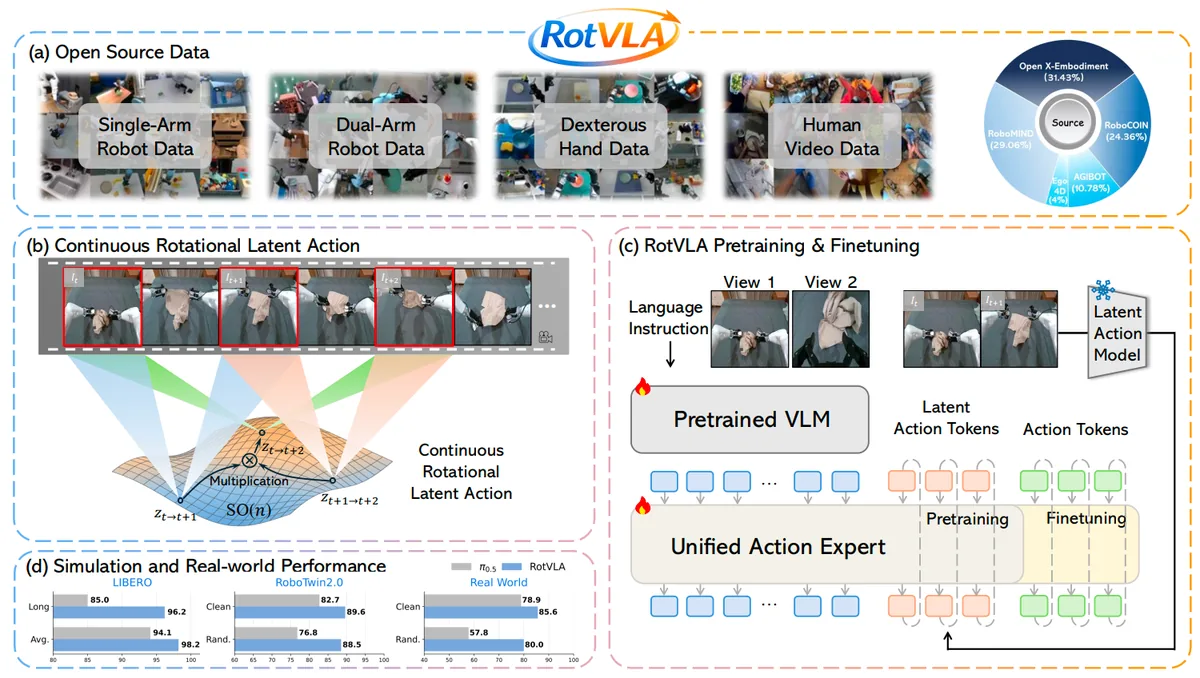
RotVLA:跨本体数据、旋转隐动作表示与模型预训练框架

2026 · ARXIV

RotVLA: Rotational Latent Action for Vision-Language-Action Model

Qiwei Li, Xicheng Gong, Xinghang Li, et al.

Introduces a rotational latent action representation that provides a unified action representation for cross-embodiment vision-language-action model pretraining.

Lifelong Learning

Learning new knowledge over time while mitigating catastrophic forgetting.
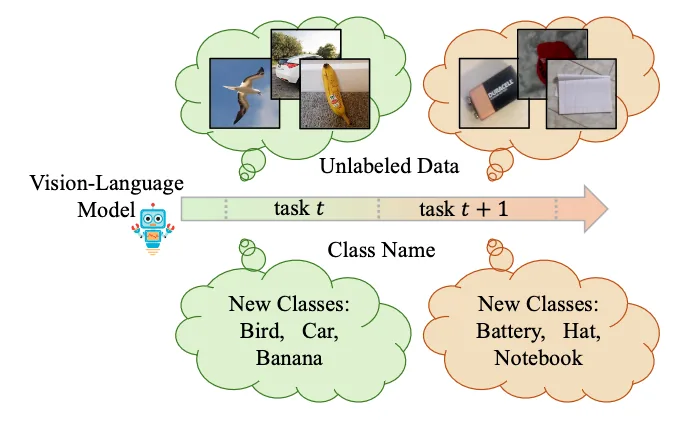
Naming to Learn:视觉语言模型利用无标注数据持续学习新类别

2026 · ICLR

Naming to Learn: Class Incremental Learning for Vision-Language Model with Unlabeled Data

Qiwei Li, Xiaochen Yang, Jiahuan Zhou*

A class-incremental learning approach for vision-language models that leverages unlabeled data through a naming-and-filtering mechanism to continually learn new classes while mitigating catastrophic forgetting.